Four GPUs, one week per run
The prototype works. Now the slowest part of our research is waiting: about a week per training run on four GPUs.
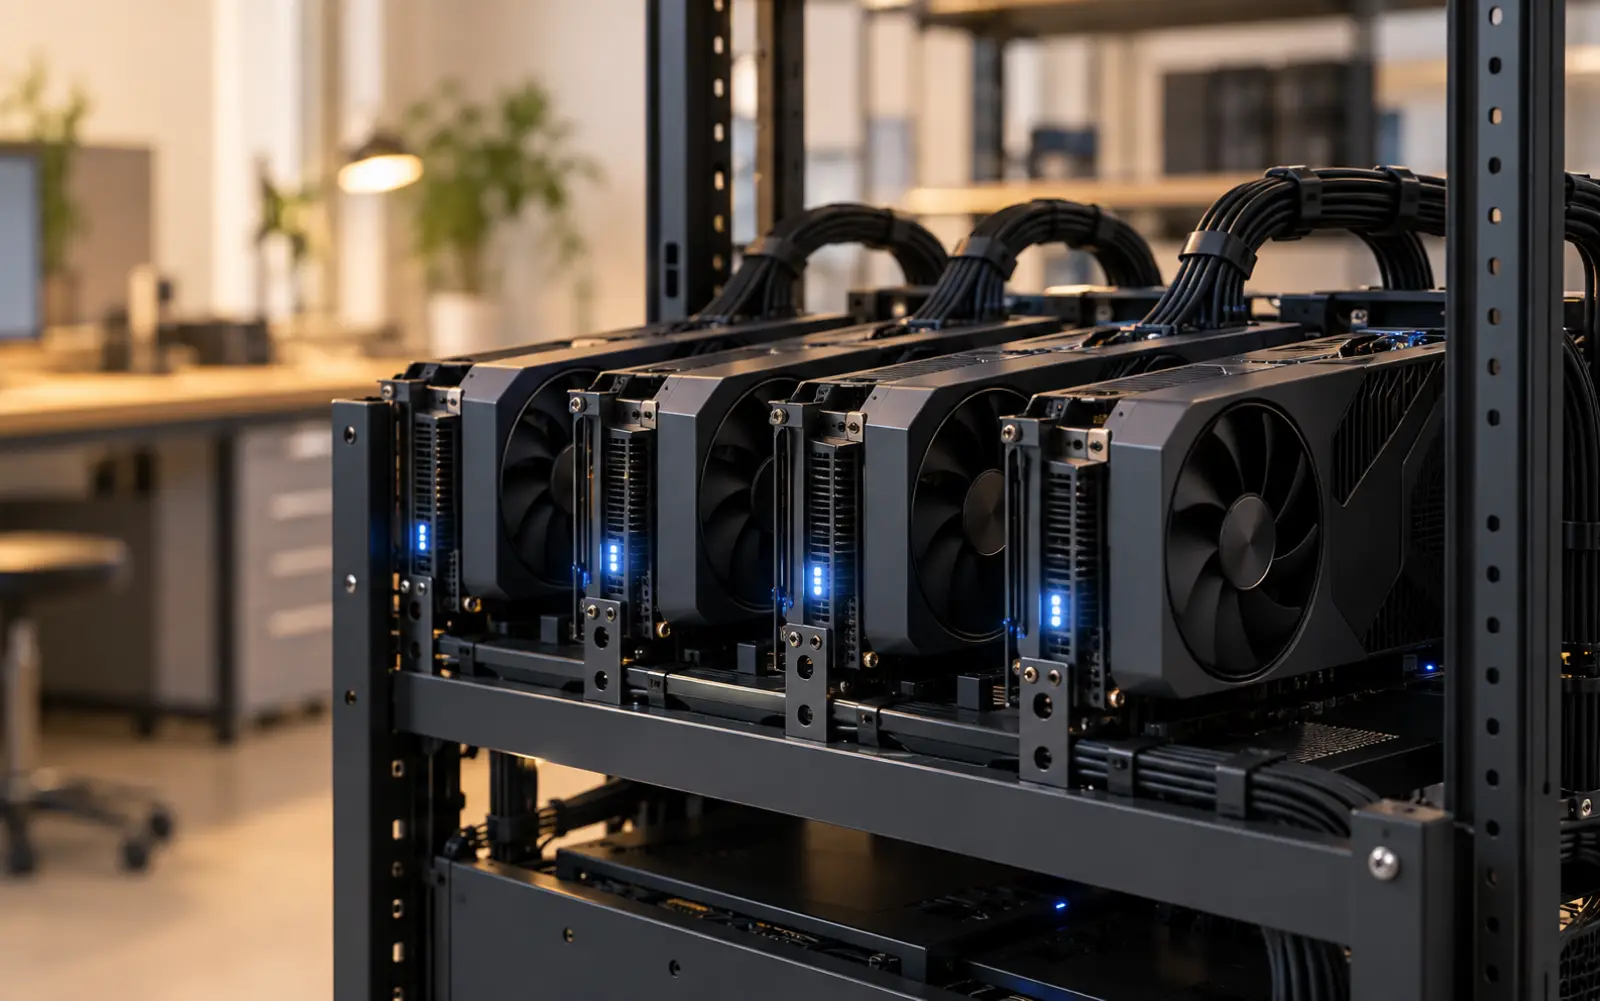
Our current setup uses four GPUs. A big training cycle takes about a week. That was enough to prove the pipeline works, but it is too slow for efficient research.
Every change to the data, the training strategy or the evaluation can cost days. Most of that time is spent waiting, not thinking.
What more compute would change
With 8 or more GPUs we could compare checkpoints side by side, repeat promising runs to separate real gains from noise, and spend more iterations on how the model sounds in Portuguese.
We do not expect linear scaling. We expect fewer days lost between decisions.
This is why we are applying to European compute and R&D programmes (see the roadmap). If you run an HPC centre or a speech research group, we would like to talk.